AI agent memory: what it is, how to build, measure and forget it
What is AI agent memory? Memory files, conversation summaries and vector search, measured in 32 harness runs — and why the hard half of memory is forgetting.
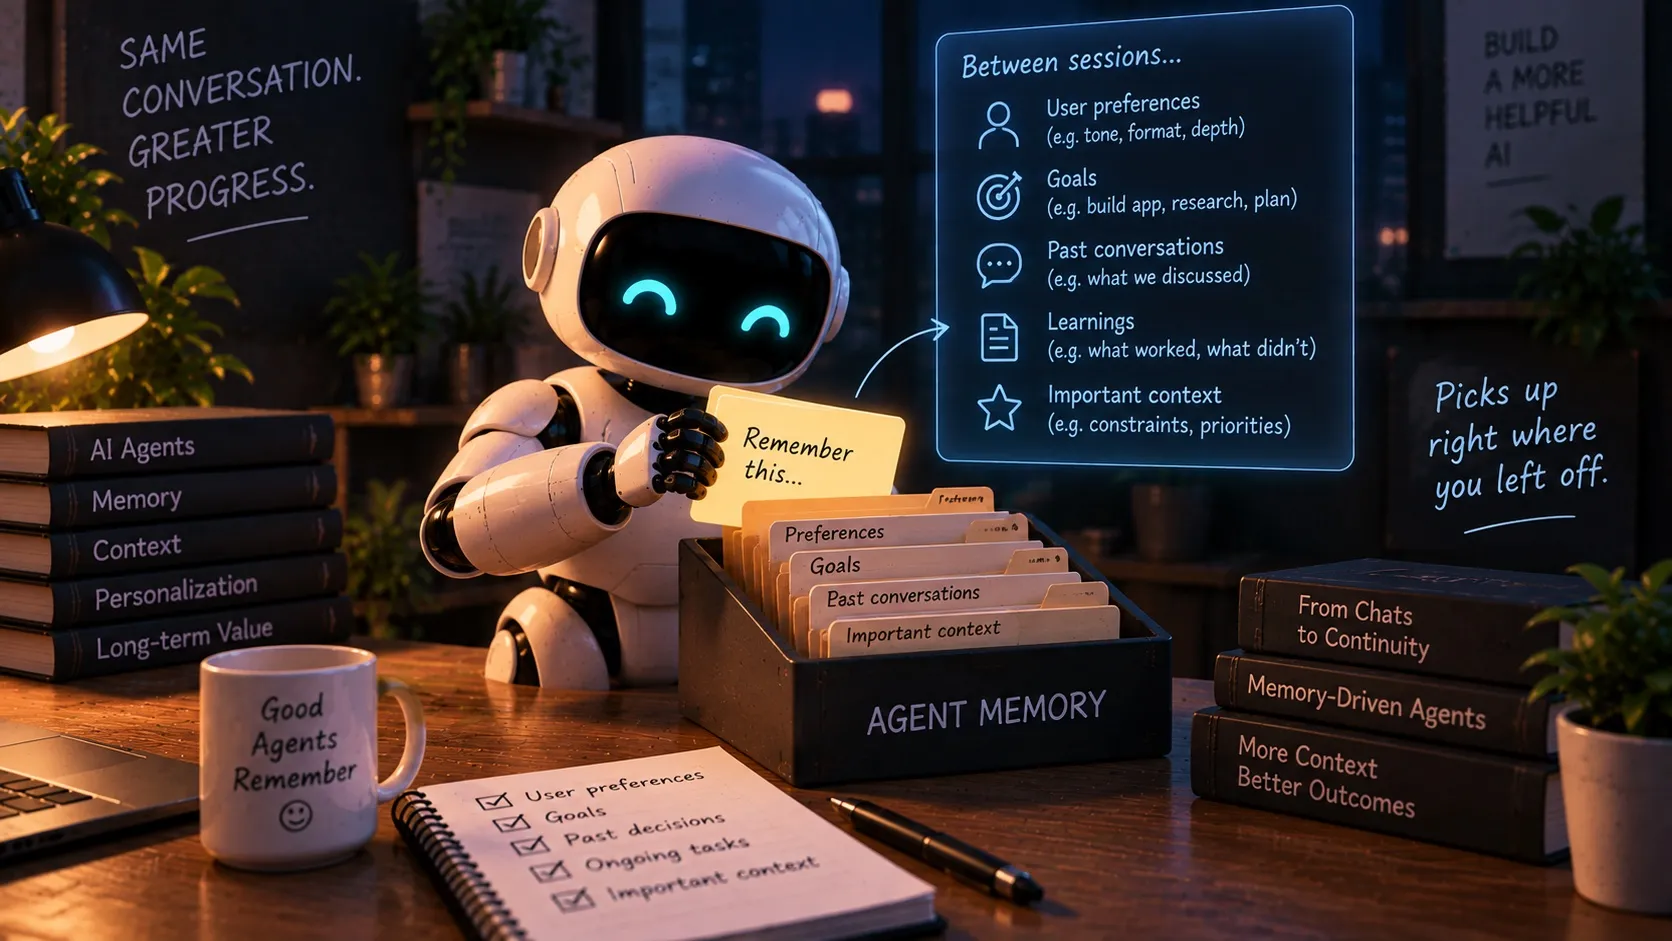
The model forgets everything between calls. That single fact is behind half of the harness engineering in this series: context engineering exists because each call starts blank, and the agent loop exists to carry state from one call to the next within a session. This essay is about the step after that: what survives when the session ends.
In the harness anatomy I gave memory one paragraph: written down, stored, re-fed into context when relevant — the difference between a brilliant contractor on day one, every day, and a colleague on year two. This essay unpacks that paragraph, measures the three common ways to build it, and lands on the part almost everyone gets wrong: not remembering. Forgetting.
What is AI agent memory?
AI agent memory is the part of the harness that writes facts down during a session, stores them outside the model, and feeds them back into context in later sessions. The model contributes nothing here. There is no neural updating, no learning between calls — a deployed model’s weights are frozen. When an agent “remembers” that your project uses tabs or that the staging database is the one you’re allowed to break, what actually happened is that software wrote a note and later pasted it back in.
Every serious harness has this organ. Claude Code reads CLAUDE.md files and keeps an auto-memory directory it writes as it works; ChatGPT’s memory feature stores facts about you and injects them into future chats; frameworks like LangGraph and the Vercel AI SDK give you a store and leave the write policy to you. Different names, same anatomy: a write path, a store, and a recall path into the context window.
That framing matters because it kills a common expectation. Memory is not a property the agent has; it is a pipeline you build. If the recall never happens, the agent knows nothing, no matter how good the notes are. And if the notes are wrong, the agent knows something false — a failure that turns out, when measured, to be subtler and worse than it sounds.
Memory is context with a write path
The recall half of memory is not new machinery. Injected memory is just context, and everything the context essay established applies to it: it competes for the same window, it costs the same tokens on every turn, and more of it is not better. If you can already engineer context, recall is the part of memory you already know how to build.
What’s genuinely new is the write path — and it is the half that decides whether memory helps or rots:
- When to save. At session end, when the model calls a save tool, or when a reviewer approves? Save too eagerly and the store fills with noise; too lazily and the expensive lesson gets re-learned next week.
- What to save. A fact, in plain words, that a future session could act on — not a diary of what happened.
- When to update or delete. Facts expire. A memory system with no update path is an archive of things that used to be true.
Two words in the anatomy essay’s definition — “when relevant” — carry the whole recall problem. Feed everything back and you’ve rebuilt the context bloat the context essay warned about; feed nothing and the store is dead weight. The next section is really a tour of four different answers to “when relevant.”
Memory files, conversation summaries, vector search
Three storage shapes cover almost every memory system in production, and each implies its own recall rule.
Memory files are curated facts in plain text — the CLAUDE.md / AGENTS.md pattern, or a MEMORY.md the agent appends to through a save tool. The recall rule is load always: the file is small because someone (human or model) curated it, so the whole thing rides along in every session. Write cost is high — curation is judgement — but recall is trivial and cheap.
Conversation summaries compress what happened: at session end, the model writes a précis of its own transcript, and the next session starts with it. This is also what harnesses do within long sessions when they compact the conversation — same mechanism, pointed across sessions instead. The recall rule is carry forward. Write cost is one model call; the risk is that the summary keeps the story and drops the load-bearing detail.
Vector search stores everything — transcripts chunked and embedded — and recalls by similarity: embed the new task, fetch the nearest chunks. This is RAG pointed at your own history. Write cost is near zero, which is the appeal; recall quality depends entirely on whether the new task happens to phrase itself like the old lesson.
There is a fourth recall rule that the three-way debate usually misses: scope. Don’t search — partition. Memory belongs to a project, a team, or a customer, and a session working in that scope gets that scope’s memory, all of it, and nothing else. Claude Code’s per-project CLAUDE.md is scoped recall. Scope answers “when relevant” structurally: relevance was decided when the note was filed, not when it’s fetched.
These aren’t competitors so much as layers. A real system typically scopes first, keeps a curated file per scope, and reaches for embedding search only when the store is too big to load — which, for a single project’s durable facts, it rarely is. The design I’d recommend before any vector database is exactly that: one scoped, curated, dated document per unit of work that recurs — rewritten rather than appended to, with a version number so changes are traceable and a size bound that forces curation the way a full notebook forces a decision about what matters. None of that is exotic machinery: a text file, an editor, a limit and a filing rule.
Why forgetting is the harder half
Here is the asymmetry that makes deletion, not storage, the hard engineering problem.
A missing memory costs a re-derivation. The agent doesn’t know the CSV encodes dropouts as -999, so it looks, finds out, and pays some tokens — the price of day one, again. Annoying, bounded, and visible.
A stale memory costs you where nothing can contradict it. When a false note collides with a live source of truth — the repo, the data — a good model can notice and re-check, and you pay the tax in verification tokens (the experiment below measures exactly that). But when the note is the only source — a preference, a decision, a rule someone said in a chat — there is no collision to notice. The agent builds on the falsehood, nothing about the run looks unusual, and the cost stays invisible until something downstream breaks.
That asymmetry has three practical consequences:
- Persist only what can’t be re-derived. Decisions, preferences, the rule an ops team told you in a chat, the gotcha that isn’t documented anywhere. Everything the repo already records — code structure, current behaviour, things a
grepfinds — should be re-derived, because the repo is always current and the note about it starts aging the moment it’s written. My own instructions for this go in the write policy: don’t save what the codebase already knows. - Date everything. A fact with a date can be distrusted on schedule; an undated fact looks eternally fresh. “As of 2026-07-10” tells a future session exactly how far to trust it.
- An append-only store is a stale store on a delay. If the only operation is save, the store grows until it bloats the context and contradicts the live repo — and the tool design essay already showed what dumping un-curated bulk into context does to cost. Update and delete are not nice-to-haves; they’re the mechanism by which a memory stays true.
The experiment below puts numbers on both halves: an agent given one out-of-date fact the repo can contradict, sitting next to three rules nothing can.
Adding memory to the Node.js harness
Time to measure. The build extends the Node.js harness this series keeps growing, on the weather-station project from the context essay: readings.csv, 5,760 rows, 4% of them -999 dropout sentinels that poison any average that includes them.
The design is two sessions, run for real against Claude Opus 5 and Haiku 4.5:
- Session 1 — learn. The agent fixes
report.js, which averages the sentinel rows (mean temperature: -21.89 °C). The prompt also states three ops rules that exist nowhere in the repo: never modifyreadings.csv, keep output inkey: valuelines, print averages with one decimal. The harness gives it one new tool,save_memory, which appends a fact to a memory file stored outside the project — memory belongs to the harness, not the repo. - Session 2 — pay off. A fresh process, no history, gets a related task: write
monthly.js, a per-month rollup of the same CSV. The sentinel gotcha applies in full, the ops conventions apply, and nothing in the prompt mentions either.
The whole build is one tool and two lines. The write path:
{
  name: "save_memory",
  description:
    "Append one durable fact to your long-term memory for this project. " +
    "Stored by the harness, outside the project folder, and shown to you " +
    "at the start of future sessions here. Save facts a future session " +
    "could not easily rediscover: gotchas in the data, decisions made, " +
    "rules the ops team gave you. One short fact per call.",
  input_schema: {
    type: "object",
    properties: { fact: { type: "string" } },
    required: ["fact"],
    additionalProperties: false,
  },
  strict: true,
}
And the recall path, at the top of the loop:
const memory = await readFile(memoryFile, "utf-8").catch(() => "");
const system = memory
  ? `${BASE_SYSTEM}\n\nYou have worked in this project before. Your project memory:\n\n${memory}`
  : BASE_SYSTEM;
That’s the entire organ. Everything else is policy — what to save, and when to stop trusting it.
The two kinds of knowledge in session 1 are the point of the design. The sentinel is a fact the repo records — an agent can always re-derive it. The ops rules are facts only the conversation held — no amount of looking at the repo recovers them. Run session 2 with and without memory, and each claim from the first half of this essay gets its own probe: what actually needs persisting, what memory really buys for the rest, and — with one planted stale fact later — what happens when a note goes wrong in each category.
Between the two sessions, the only variable is the recall arm — what the harness injects into the system prompt:
| Arm | What session 2 sees |
|---|---|
| none | nothing |
| file | the memory file the agent wrote via save_memory |
| summary | the model’s own end-of-session summary of session 1 |
| vector | top-6 transcript chunks by cosine similarity to the new task (local MiniLM embeddings) |
Same harness, same tools, same task, same fixed project state; three runs per arm per model. (The full experiment is 32 runs: one learn session per model, these 24, and six stale-memory runs below.) Both models wrote good memories in session 1, unprompted about form: Opus saved four specific bullets (down to the correct post-fix output values); Haiku saved two. Each file is under a kilobyte — recall itself costs almost nothing.
What the arms did
Every value below is the mean of three runs:
| model | arm | correct numbers | key: value | one decimal | turns | input tokens | $ per run |
|---|---|---|---|---|---|---|---|
| Opus 5 | none | 3/3 | 0/3 | 3/3 | 10.3 | 42,356 | $0.300 |
| Opus 5 | file | 3/3 | 3/3 | 3/3 | 7.0 | 28,195 | $0.214 |
| Opus 5 | summary | 3/3 | 3/3 | 3/3 | 5.0 | 19,518 | $0.164 |
| Opus 5 | vector | 3/3 | 3/3 | 3/3 | 8.0 | 40,278 | $0.287 |
| Haiku 4.5 | none | 3/3 | 0/3 | 0/3 | 12.7 | 109,348 | $0.122 |
| Haiku 4.5 | file | 3/3 | 3/3 | 3/3 | 9.3 | 94,988 | $0.104 |
| Haiku 4.5 | summary | 3/3 | 3/3 | 3/3 | 6.3 | 44,672 | $0.051 |
| Haiku 4.5 | vector | 3/3 | 3/3 | 3/3 | 10.0 | 97,386 | $0.106 |
Three findings, one of them a negative worth printing.
Memory never changed correctness. All 24 runs got the numbers right, zero sentinel leaks — because this repo documents the sentinel in README.md, config.json, docs/sensor-faq.md, and the fixed report.js. A fact the repo records gets re-derived reliably; storing it in memory saved exploration, not accuracy. That is the persist-vs-re-derive rule showing up in the data.
Memory was the only carrier of the conversation-only knowledge. The two format conventions — stated once in session 1’s chat, recorded nowhere in the repo as rules — were followed in full 18/18 across the three memory arms and 0/6 without. (One nuance the table shows: the fixed report.js does print one decimal, and Opus copied that style even without memory. A style can be inferred from the repo; that it’s a rule — the thing that makes it binding on a new script — only memory carried.) The third rule, never modifying readings.csv, no run in any arm broke — the verifier hashed the file every time. The no-memory runs weren’t careless; they produced correct rollups as tab-separated tables, which is a perfectly good format for anyone except the ops dashboard that parses key: value lines:
$ node monthly.js   # no-memory arm — correct, and useless to ops
month	readings	temp_c	humidity	wind_kph
2026-07	4293	18.4	51.7	10.9
2026-08	1239	18.4	52.1	11.1
$ node monthly.js   # file arm — the convention survived the session
2026-07_mean_temp_c: 18.4
2026-07_mean_humidity: 51.7
2026-07_mean_wind_kph: 10.9
2026-08_mean_temp_c: 18.4
2026-08_mean_humidity: 52.1
2026-08_mean_wind_kph: 11.1
(Both months really averaging 18.4 °C is not a typo — the dataset’s diurnal cycle dominates, and the verifier checks all six values independently.)
The summary beat the curated file on cost — and vector search barely paid for itself. The summary arm halved the task: Opus went from 10.3 turns and $0.300 to 5.0 turns and $0.164; Haiku from $0.122 to $0.051. Reading the summaries explains why: the model’s précis of its own session included a map — the file list, the CSV’s shape, the verified output values — so the next session skipped exploration entirely, while the lesson-shaped memory file still left it to rediscover the layout. The vector arm recalled the right facts (the retrieved chunks included session 1’s prompt, ops rules and all) but wrapped them in ~3 KB of raw transcript — among them the pre-fix buggy report.js — and saved Opus all of 4%. Transcript-grained recall re-imports what you already outgrew.
The usual caveats, plainly: three runs per arm, one task family, one small project, two models. The vector arm is honest but minimal — local MiniLM embeddings over per-entry transcript chunks, not a tuned retrieval stack. And the store here is small enough to load whole, which is exactly the regime where files and summaries shine.
The stale-memory isolate
Then the forgetting experiment. Same session-2 task, file arm — but the memory is planted, and one fact in it is out of date: it claims the dropout sentinel is -99, when the data in front of the agent uses -999 and the repo says so everywhere the agent might look. This is exactly the failure an append-only store manufactures: a fact that was true once, kept past its expiry, contradicting the live repo.
I expected wrong numbers. I got something more precise. All six runs caught the lie. Both models noticed the contradiction, checked the repo, and sided with it:
[Opus 5, stale arm, turn 2]
Note a discrepancy: my memory says the sentinel is -99, but report.js's
comment says -999. Let me check the actual config and data.
[turn 3]
My memory of "-99" is wrong — README and config both say -999.
Let me verify against the actual data.
[turn 4]
Confirmed: sentinel is -999 (228 rows), and there are no -99 values at all.
But the arbitration wasn’t free. Resolving one stale fact cost Opus $0.280 per run against the fresh file’s $0.214 — a 31% surcharge that hands back most of what memory saved, spent re-verifying a repo it would otherwise have trusted its notes about. Haiku’s toll was smaller at the till ($0.110 against $0.104) but showed up as two extra turns of the same checking. A stale memory didn’t poison the output here; it poisoned the economics, and turned the memory from a shortcut back into a lead to double-check.
The sharper result is what the models didn’t check. The same planted memory carried the three ops conventions, and all six runs obeyed them without a single verifying look — there is nothing in the repo that could confirm or refute a rule like “ops reads one decimal.” Sentinel value: checkable, checked, caught. Conventions: unverifiable, swallowed whole. Had the ops team changed the rules since, every run would have silently followed the old ones.
That’s the real shape of the forgetting problem, and it’s worse than “stale memory makes agents wrong.” The facts memory exists to carry — decisions, preferences, rules stated in a conversation — are precisely the facts the world can’t contradict. An agent can fact-check its memory of a repo against the repo. Its memory of you, it has to trust. Deletion discipline isn’t hygiene; for that class of fact, it’s the only defence there is. (Two caveats, stated plainly: this repo documents the true sentinel loudly, and n=3 per model — in a project where the truth isn’t written down at all, the checkable class shrinks toward zero.)
How to forget: a review pass, demonstrated
Forgetting doesn’t need new machinery either — it’s one more prompt. At session end (or on a schedule), the harness hands the agent its own memory file with one instruction: verify every entry against the project as it exists right now; keep what’s still true, correct what the project contradicts, delete what no longer earns its place. I ran exactly that pass over the planted stale file, once per model:
$ node forget-pass.mjs   # session-end memory review, Opus 5, 6 turns
before:
- The BSL-04 logger writes -99 in every numeric column when the
  sensor array drops out … filter out rows where a value is -99 …
after:
- The BSL-04 logger writes -999 in every numeric column when the
  sensor array drops out … filter out rows where a value is -999 …
  The value comes from sentinel_value in config.json — read it from
  there rather than hardcoding.
Both models corrected the sentinel entry against the repo and left the ops rules standing; Opus upgraded the entry while it was in there, pointing future sessions at config.json instead of a hardcoded value. One pass cost about $0.13 on Opus and $0.05 on Haiku — against a verification tax charged on every future session that reads the stale file. (One run per model — a demonstration of the mechanism, not a measurement.) The limit is the one from the previous section: a review pass can only repair what the project can contradict. For the unverifiable entries, the pass has exactly one lever, and it’s the date — which is why every entry should carry one.
Common agent memory mistakes
- Saving everything. An archive is not a memory. If the write path has no judgement in it, the recall path inherits the noise — and you pay for it in tokens on every session.
- Never deleting. Every fact ages. A store with no update or delete operation converges on wrong; the only question is when.
- Undated facts. Without a date, staleness is undetectable. With one, it’s a maintenance schedule.
- Trusting memory over the live repo. Memory should carry what the repo can’t tell you. When a memory and the repo disagree, the repo — always current — wins, and the write policy should say so in as many words.
- Summaries that keep the story and lose the numbers. A summary of “we fixed the averaging bug” without what the sentinel value was recalls the plot and forgets the lesson.
- Searching when you could scope. If memory naturally belongs to a project, team or customer, partition it there and load it whole. Embedding search is for stores too big to curate — don’t start with it.
Context decides what the agent sees; memory decides what it gets to keep. The mechanics are the easy part — a file, a save tool, a block of recalled context. The discipline is the hard part: save what can’t be re-derived, date it, and delete it when it stops being true. An agent that remembers everything isn’t experienced. It’s superstitious.