Context engineering: what your AI agent sees decides what it does
Context engineering: what an AI agent's context window holds, the five levers that control it, and a real harness cut from 859,699 to 23,953 tokens.
The first essay in this series, What is an AI agent harness?, called a model a brain in a jar, and the harness the body around it. The last one, Build your first AI agent harness in Node.js, built that body in plain JavaScript: hands to read, run, and edit, a spine that loops, and reflexes that ask before acting.
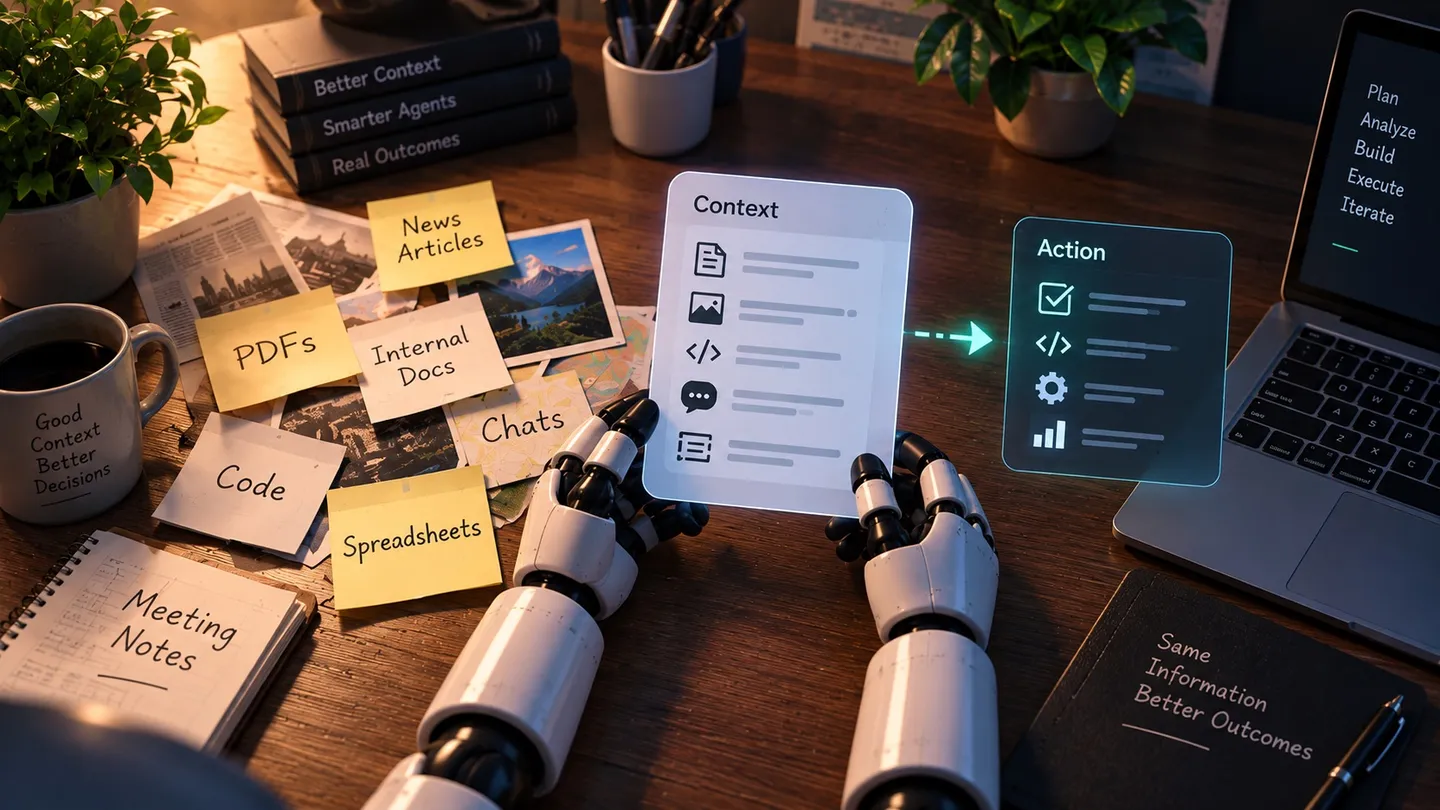
We skipped one part of the anatomy, and it’s the part most teams get wrong first: the senses. A brain in a jar can’t look around. It only knows what you hold up to the glass. In an AI agent, what you hold up to the glass is called the context, and deciding what goes there is called context engineering.
This essay does it in two halves. First, the idea: what the context is, why it’s the thing that decides how an agent behaves, and the five levers you have to control it. Then the proof: the same Node.js harness from last time, a real bug, and six runs with real numbers, where each lever changes the result.
What is context in an AI agent?
Context is everything the model can see at the moment it takes a step: the instructions, the tool descriptions, the conversation so far, and every result its tools have returned. Nothing else exists for it.
An LLM is stateless: it has no memory between calls. Every time the harness wants the model to take a step, it sends one package of text, the model replies, and that’s it. The next step sends a new package. That package is the context window, and it’s the model’s whole world. If something isn’t in it, the model doesn’t know it exists.
In an agent, that package has six parts:
- The system prompt. Who the agent is and how it should behave. Written once, sent every turn.
- Tool definitions. The name, description, and input shape of every tool it can use. The model only knows a tool exists because it’s described here.
- Rules and memory. Project knowledge the model can’t discover by itself: conventions, gotchas, what not to touch. Tools like Claude Code load this from files like
CLAUDE.mdorAGENTS.md. - The conversation so far. Your request, and every reply and tool call the model has made since.
- Tool results. Everything the tools returned: file contents, command output, search results. In a working agent, this is usually the largest part by far.
- Retrieved content. Anything the harness looked up and added on the model’s behalf, like the relevant section of the docs.
The first three parts are the same on every turn. The last three change, and two of them only ever grow. Every tool call adds a result, every reply adds to the history, and all of it gets sent again on the next turn.
What is context engineering?
Context engineering is deciding what goes into each of those six parts of the context window, and what stays out, on every turn of an agent’s loop.
Context engineering vs prompt engineering
The two get mixed up, but they work at different levels. Prompt engineering is about the words in one message: how you phrase an instruction so the model understands it. Context engineering is about everything the model sees, turn after turn, while it works: which files it reads, how much of each tool result it gets, what rules ride along, and what gets dropped as the conversation grows.
A perfect prompt can’t save an agent whose window is full of noise. For a single question to a chatbot, prompt engineering is most of the job. For an agent that loops, reads files, and runs tools, the prompt is one small part of the window, and context engineering is the rest.
Why context engineering matters
If the model has everything it needs in the window, why worry? For three reasons.
You pay for it again every turn. Because the model is stateless, the loop resends the whole window each time, so a big tool result doesn’t cost you once. It costs you on every turn after it arrives. A 100,000-token file read on turn 2 of a 10-turn task is paid for nine times.
The window has a ceiling. Every model has a maximum context size. Fill it and the request fails outright. Real projects have log files, lockfiles, and data dumps that can fill a window in a single read.
More context isn’t better context. This is the one people don’t expect. Researchers have measured it. Lost in the Middle showed that models make less use of information buried in the middle of a long input. Chroma’s Context Rot report found performance drops as input grows, even on simple tasks. A window stuffed with noise is like a desk buried in paper: the answer is somewhere on it, but that’s not the same as seeing it.
So the goal isn’t to give the model everything. It’s to give it the smallest set of information that lets it do the next step well.
How to control an AI agent’s context: five levers
A harness has five ways to shape what the model sees. None of them are exotic. They’re ordinary code decisions most people make by accident.
1. Budget: cap what comes in. Every tool result gets a size limit, enforced in code. When a result is cut, the harness says so, and says how to see more: “showing 139 of 5762 lines, use offset/limit to read a range.” This is the most important lever, and the cheapest. A limit in code can’t be ignored. A polite line in the prompt (“please don’t read big files”) can.
2. Retrieve: look things up instead of reading everything. Give the agent ways to find what it needs without pulling in the whole haystack: read a line range, search for a pattern, run grep or head. RAG (retrieval with embeddings and a vector store) is the same idea for text you can’t search by exact words. For code and logs, search and ranged reads get you most of the way. The principle: bring the answer into the window, not the raw data.
3. Instruct: write down what it can’t discover. Some knowledge isn’t in the files. “-998 means the sensor is warming up.” “Never edit the raw data.” “Round to one decimal.” Put facts like these in a short rules file that loads into every turn. Keep it short, because it’s paid for on every turn too. If the model could find something out by reading the code, leave it out.
4. Order: stable first, changing last. Put the parts that never change (system prompt, tools, rules) at the start, and the growing conversation at the end. Model providers can cache an unchanged prefix, and cached tokens cost a fraction of the normal price. Anything that changes every turn, like a timestamp, belongs at the end, or it breaks the cache for everything after it.
5. Forget: remove what’s no longer needed. Long sessions pile up context even when every single piece is small. Eventually the harness has to drop something. It can clear old tool results, or compact: have the model summarize the history, then continue from the summary. Both work. Both lose information. That makes forgetting the riskiest lever, and the one to reach for last.
That’s the theory. Here’s what happened when I tested it.
The experiment
I used the harness from the Node.js build essay, unchanged except for a one-line system prompt and one line that prints how many tokens the model reads on each turn:
console.log(` [turn ${iteration + 1}: model read ${response.usage.input_tokens.toLocaleString()} tokens]`);The patient is a small weather-station project. report.js averages a day of temperature readings from readings.csv (5,760 rows from four sensors, one reading a minute, 167 KB) and prints the result in Celsius. It prints 13.0°C. The ops team says the day averaged about 21°C.
The bug is in the data, not the code. When a sensor drops out, the firmware writes -999 instead of a temperature. That happens 81 times, and each one drags the average down. You can’t find it by reading report.js. You have to look at the data, and the data is the biggest thing in the folder. That’s the trap.
Every run below gets the same task: “report.js prints today’s average temperature from readings.csv. The ops team says it should be about 21°C, but it prints about 13. Find out why, fix it, and rerun report.js to confirm.” In the transcripts, I’ve dropped the y/n permission lines (every action was approved) and shortened long commands to ….
Run 1: a careful model
On Opus 5, the harness fixed it in 9 turns and 20,747 tokens in total. What’s interesting is what it didn’t do: it never opened the CSV.
Claude wants to: run_command({"command":"head -5 readings.csv; echo ---; wc -l readings.csv"})
  [turn 3: model read 1,578 tokens]
…
Claude wants to: run_command({"command":"awk -F, '…count the -999 rows…' readings.csv"})
  [turn 6: model read 2,620 tokens]
…
Fixed — it now prints 21.4°C.
  [total: 20,747 input tokens across 9 turns]
It looked at five lines, counted the rest, and had awk compute over all 5,760 rows and send back a summary. The meter still climbed every turn, from 696 tokens to 3,702, because the whole window gets resent each time. But nothing big ever entered it. Opus applied the retrieve lever by itself.
It’s nice to see. But a harness that only works when the model is disciplined isn’t finished.
Run 2: the flood
In production, you don’t run every task on your most expensive model. Routine work goes to smaller, cheaper ones. So I switched to Haiku 4.5 and changed nothing else:
  [turn 1: model read 824 tokens]
Claude wants to: read_file({"path":"report.js"})
Claude wants to: read_file({"path":"readings.csv"})
  [turn 2: model read 121,933 tokens]
Claude wants to: read_file({"path":"convert.js"})
  [turn 3: model read 122,068 tokens]
…
  [turn 8: model read 123,554 tokens]
The report now correctly shows 21.39°C, which matches the ops team's
expectation of about 21°C.
  [total: 859,699 input tokens across 8 turns]
One read took the meter from 824 tokens to 121,933, and it stayed there for every turn after. It made the same one-line fix as Opus, and read 859,699 tokens doing it: 41 times as many. At list prices, that’s about 86 cents of input for a one-line fix. Opus spent about 10 cents, even though its tokens cost five times more.
All three problems from earlier showed up in this one run. It paid again every turn: six more turns at about 122,000 tokens each. It came close to the ceiling: Haiku’s window is 200,000 tokens, so one read filled 61% of it, and a file twice as big would have failed the run. And more context wasn’t better: with all 5,760 rows in view, it still went down a wrong path first, questioning the column index, before saying “Wait, let me recalculate.”
The cheap model turned out to be the expensive one, and model choice had little to do with it. Nothing in the harness stopped a 167 KB file from landing in the window.
Run 3: budget and retrieve
Levers 1 and 2, added to the harness. Every tool result is capped at 4,000 characters, and a cut says what’s missing:
function bound(text, hint) {
  if (text.length <= MAX_TOOL_CHARS) return text; // MAX_TOOL_CHARS = 4_000
  const kept = text.slice(0, MAX_TOOL_CHARS);
  return `${kept}\n\n[truncated: showing ${kept.split("\n").length} of ${text.split("\n").length} lines. ${hint}]`;
}
read_file also got optional offset and limit inputs for reading a range of lines, and there’s a new search tool that returns the first 20 matching lines. Same Haiku, same task:
  [turn 1: model read 987 tokens]
Claude wants to: read_file({"path":"report.js"})
Claude wants to: read_file({"path":"readings.csv"})
  [turn 2: model read 4,195 tokens]
The CSV has temperatures around 65-66°F, and there are also some
sentinel values `-999` which appear to be error/invalid readings.
…
After fix: 21.39°C (correct, matching the expected ~21°C from the ops team)
  [total: 23,953 input tokens across 6 turns]
It made the same move, reading the whole CSV, but the harness only let 4,000 characters through. 859,699 tokens became 23,953, 36 times less, with the same fix. Haiku now used about as many tokens as Opus had, because the harness supplied the discipline the model didn’t have.
Two honest notes. It got lucky: a -999 happens to appear eleven minutes into the day, inside the first 4,000 characters. If the first dropout had been at noon, it would have needed search or a ranged read to find it. That’s what those tools are for. And it was slightly wrong: “temperatures around 65-66°F” is true only of the pre-dawn rows it saw. The daily average is about 70.5°F. A truncated view is a partial view, which is why the truncation notice matters. A harness that cuts silently lets the model mistake the first page for the whole file.
Run 4: instruct
Lever 3. I added a rules file to the project:
# Station project rules

- readings.csv is raw firmware output. Never edit it.
- The firmware writes two sentinel values into temp_f: -999 (sensor offline)
  and -998 (sensor warming up). Neither is a temperature.
- Report temperatures in °C, rounded to one decimal place.
The harness appends it to the system prompt if it exists. -998 appears nowhere in today’s data, and the rounding rule is written down nowhere else. The model can’t discover either one. Here’s the fix Haiku wrote with budgets alone, and then with budgets plus the rules:
# budgets only
+ const temps = rows.map((row) => Number(row.split(",")[2])).filter((t) => t !== -999);

# budgets + rules file
+ const temps = rows.map((row) => Number(row.split(",")[2])).filter((t) => t !== -999 && t !== -998);
+ console.log(`Daily average: ${fahrenheitToCelsius(average).toFixed(1)}°C`);
Same model, same bug, different context, different code. The second fix handles a failure that hasn’t happened yet and follows a convention the first run had no way to know. The rules changed how it worked, too. It read only the first 20 lines of the CSV and grepped for both sentinel values. The whole run took 19,671 tokens.
The rules have a cost. Turn 1 read 1,065 tokens instead of 987, and those extra 78 tokens get paid on every turn. Five lines is cheap. A rules file that restates the whole codebase is a flood you’ve built in on purpose.
Runs 5 and 6: forget
Lever 5. To test it, I took the budgets off again so Haiku would flood its window, and tried to recover by forgetting.
Clearing came first: before each turn, replace all but the two most recent tool results with [cleared]. The meter looked great, dropping from 121,929 tokens on turn 2 to 1,346 on turn 3. The agent didn’t look great. The CSV was cleared one turn after it arrived, before the model had learned anything from it, and its only note from that turn was a wrong theory. It spent its next ten turns re-deriving what it had already seen: checking the wrong column, dumping bytes with od, running tail on the CSV. Then it hit the iteration cap with nothing fixed, after 143,853 tokens. A smarter version, whose stubs said exactly what was cleared and how to get it back, failed the same way.
The lesson: clear what’s stale, not what’s live. A result the model has finished with is safe to drop. A result it’s still working through is its working memory, and the harness can’t tell the two apart by age.
Compaction came next: when the history gets too big, ask the model to write working notes, then restart the conversation with only the task and those notes. This one fixed the bug, eventually. Its first set of notes saved a wrong theory: “The fahrenheitToCelsius function in convert.js is likely wrong.” A summary keeps whatever the model believed when it wrote it, right or wrong. It compacted three times, and re-read the whole CSV after the first two restarts, before it finally made the fix. Total: 376,734 tokens, less than half the flood, but 16 times what budgets needed.
The Anthropic API now offers server-side versions of both moves: context editing clears old tool results, and compaction summarizes history once it passes a threshold. I built mine by hand to show the mechanics, and I haven’t tested the server-side versions against this demo. They’re likely tuned better than my twenty lines. The lesson holds either way: forgetting is lossy, so use it last. An agent that never floods its window rarely needs to forget anything in a hurry.
The scoreboard
Two models, one bug, and the context decided every outcome: 20,747 tokens or 859,699, a fix that anticipates -998 or one that doesn’t, a clean finish or an iteration cap. The model supplied the intelligence each time. The harness decided what it got to see.
Put the runs side by side and one lesson stands out: prevention beats cure.
The problem in every Haiku run was the same. One read put the whole CSV, about 122,000 tokens, into the window, and because the model is stateless, the harness resent all of it on every turn after that. There are two ways to deal with that.
Prevention: don’t let the big file in. The harness caps every tool result, so the flood never enters the window and there’s nothing to clean up later. That run fixed the bug in 23,953 tokens.
Cure: let it in, then try to get rid of it. I tried two ways:
- Clearing deleted old tool results from the window. It deleted the CSV before the model had finished learning from it, so the model got confused and ran out of turns. 143,853 tokens, no fix.
- Compaction had the model summarize everything so far, then start over from the summary. It got there, but the first summary recorded a wrong guess, and it re-read the file twice along the way. 376,734 tokens, fixed.
Stopping the flood at the door cost 16 times less than cleaning it up afterwards, and it was more reliable. Cleaning up always throws information away, and you don’t get to choose exactly what. It’s like packing a suitcase: it’s far easier not to pack what you don’t need than to unpack at the airport and decide what to throw out, because in a rush you throw out the wrong thing.
The best token is the one you never put in the window.
Common context engineering mistakes
Most of these showed up in the runs above. For each one, here’s the mistake, what it cost, and the fix.
- Choosing a model by its price per token. The cheapest model in this experiment cost the most: Haiku’s tokens are five times cheaper than Opus’s, and it still spent about 8× more on the same fix. Fix: judge a model by what the whole task costs, and make the harness keep that cost down.
- Trusting the model to keep its own window clean. Opus sampled the CSV carefully. Haiku read all of it. Same harness, same task, 41 times the tokens. Fix: assume some model, someday, will read the biggest file in the folder, and build the harness for that day.
- Putting limits in the prompt instead of the code. “Please don’t read large files” is a request, and the model can ignore it. Fix: cap every tool result in code. A limit in the harness can’t be ignored.
- Cutting output silently. With only the first rows in view, Haiku decided the temperatures were “around 65-66°F”. The day actually averaged 70.5°F. Fix: every cut says what’s missing and how to get it, like “showing 139 of 5762 lines, use offset/limit to read a range.”
- Treating a big context window as permission to fill it. One file filled 61% of Haiku’s window, and research shows models get worse as the window fills. Fix: give the agent ways to look things up (search, ranged reads,
head,grep) and bring answers into the window, not raw data. - Stuffing the rules file. The five-line rules file cost 78 tokens on every turn. A file that restates the whole codebase costs thousands, every turn, for things the model could read when it needs them. Fix: write down only what the model can’t discover from the files.
- Forgetting too early. Clearing old tool results dropped the CSV before the model had learned anything from it, and the agent hit the iteration cap without a fix. Fix: clear what’s stale, never what the model is still working on. Reach for forgetting last.
- Trusting a summary as if it were the truth. The first compaction saved a wrong theory about
convert.js. A summary keeps whatever the model believed, right or wrong. Fix: treat compacted notes as leads to re-check, not as facts, and avoid compaction by not flooding the window in the first place. - Putting changing content first. A timestamp or request ID at the top of the system prompt changes the start of the window every turn, so the API can’t cache any of it. I didn’t measure this one here. Fix: stable parts first (system prompt, tools, rules), changing parts last.
- Never looking at the number. None of the other mistakes are visible without a meter. Fix: log the tokens the model reads on every turn, from day one.
The ordering mistake is really about cost, and it gets its own essay later in this series, on why agents cost too much.