Decoding TypeSafe's Jev: why it's fast, cheap, and can't hallucinate
TypeSafe AI's Jev drops chat and the token loop for typed, calibrated decisions — how it works, why output tokens are free, and what '0% hallucination' means.
Two days ago a company came out of stealth with a frontier AI model that refuses to talk.
No chat window, no prose, no explanations — the model is physically incapable of producing a sentence. The company is TypeSafe AI, the model is called Jev, the seed round is $40M led by DCVC, and the CEO is Diogo Almeida — fourth author on the InstructGPT paper, the work that taught models to follow human instructions and made ChatGPT possible. Which makes the pitch delicious: one of the people who taught AI to talk to us has decided that talking was the mistake.
I spent time pulling apart everything they’ve published — the launch post, the docs, the founder’s talks — because underneath the launch noise sit three genuinely interesting engineering questions. How does a model with no text output actually work? Why does that make it fast enough to give output away free? And is “0% hallucination” real or a magic trick? Let’s take them in order.
A form, not an essay
When your software asks a chat model something — say, “which team should handle this support ticket?” — it gets back a paragraph: “Great question! Based on my analysis, this seems like it could be a billing issue, although…” Your code then has to dig the actual answer out of the prose, and sometimes the digging fails. Every developer who has parsed LLM output in production knows this tax.
Jev deletes the paragraph. You send the ticket plus the allowed answers — billing, technical, account — and it returns one of those answers with a probability attached. Nothing to parse, because nothing free-form was ever generated. Their docs put it flatly: System One models do not write replies, produce code, or generate explanations — they return typed values your code can branch on directly.
The analogy that made it click for me: a chat model is an essay writer; Jev is a multiple-choice answer sheet. It can only bubble in options you printed on the sheet — and a bubbled sheet cannot be misread the way an essay can. That’s the entire meaning of “chatless.”
The name of the model class — System One Models — tips the ambition. In Kahneman’s terms, System 1 is the fast, automatic, intuitive judgment; System 2 is slow deliberation. Chat models are being pushed toward System 2 — longer reasoning, more thinking tokens. TypeSafe went the other way: pure System 1, the snap judgment, industrialized.
The only three things it can say
Every question you send must be shaped as one of three primitives — three fixed answer shapes, straight from their docs:
- Choice — pick one from my list. “Which team should handle this ticket?” →
choice: "billing", with a probability for every option. - Score — rate it on my scale. “How frustrated is this customer?” →
score: 1.4. - Noul — their term for a true/false claim, answered with a calibrated probability. “Does this message ask for a refund?” →
noul: 0.95.
A dropdown, a dial, and a lie-detector needle. That’s the whole vocabulary. It sounds like a limitation, and it is — deliberately. Software loves forms and hates essays; the three primitives are the form fields. (Input is text-only for now — strings, JSON, arrays. No images, audio, or video yet.)
Why it’s fast — and why output tokens are free
Here is the part I find genuinely elegant, and it starts with decoding one heavy word: chat models are autoregressive. They produce text one token at a time, and each new token requires running the entire model again with everything written so far fed back in. A 200-word answer is a couple hundred sequential passes through billions of parameters. That loop is why LLM output costs money and why answers take seconds: you are paying a typist by the keystroke.
Jev throws the loop away. Because every legal answer is known up front — your dropdown options, your scale, your yes/no — it runs the model once and reads the probability of every option off that single pass. TypeSafe calls this the parallel sampler: all probabilities in parallel instead of autoregressively generating by token. One pass can even carry hundreds of separate questions about the same input simultaneously. (One edge case from the docs: option lists longer than 255 fall back to a two-stage score-then-choose pass.)
Jev isn’t a typist at all — it’s a rubber stamp. The whole answer lands in one press, so charging per letter would be absurd. And that is precisely how they price it: input $0.042 per million tokens, output free — “too cheap to meter,” in their words. You pay for what the model reads, never for what it answers. The claimed speed follows from the same fact: 70–500ms end-to-end, 40x–200x faster than frontier LLMs on these decision-shaped queries.
Both caveats belong right here, not in a footnote. The speed numbers are TypeSafe’s own, from internal evals they themselves describe as “on the higher end of real world gains.” And on the pricing, they concede — credit for honesty — that they can’t prove it isn’t subsidized by the war chest. Elegant architecture and aggressive go-to-market pricing can produce the same invoice.
Jev is not an LLM: LLM vs Jev
Everything so far, on one card — the asterisks mark TypeSafe’s own unreplicated numbers:
| Chat LLM | Jev | |
|---|---|---|
| What comes back | Free-form prose you must parse | A typed value + probability |
| Vocabulary | Anything expressible in language | Choice, Score, Noul — that’s all |
| How it’s generated | Token by token, model runs per word | One parallel pass, all answers at once |
| Speed | Seconds | 70–500ms* |
| You pay for | Input and output tokens | Input only — output is free |
| Malformed output | Possible — broken JSON, invented options | Impossible, by construction |
| Wrong answer | Possible | Equally possible (~68% right on their own benchmark*) |
| Knows how sure it is | No — fluent at any confidence | Calibrated probabilities* (the whole training bet) |
| Input | Text, images, audio, video | Text and JSON only, for now |
| Built for | Conversation, writing, code, reasoning | High-volume judgment calls inside software |
The table makes the real trade visible: Jev gives up the entire expressive range of language to buy speed, price, format guarantees, and (if the calibration holds) honesty about uncertainty. It is not a better LLM — it’s a different tool that happens to share the transformer bloodline.
The training bet: stop optimizing for applause
Architecture explains the speed. The more radical bet is in the training, and you can state it in one line: RLHF is the bug.
All the RL-acronyms just answer one question — what do you reward the model for in finishing school? RLHF, the method behind every chat assistant (and the method Almeida helped build), rewards answers that humans preferred. Reward applause and you raise a people-pleaser: fluent, agreeable, and confidently wrong often enough that a human must review its work. Almeida’s argument is that this is not incidental but structural — the “HF” in RLHF is literally the human in the loop, baked into the objective. The newer alternative, RLVR, rewards verifiably correct answers, which is why reasoning models got so good at math and code — but only where a checker exists.
TypeSafe trains with what it calls RLCD — Reinforcement Learning for Calibrated Decisions — a third objective: reward the model when its confidence numbers are honest. The mental model is a good weather forecaster. When she says 70% chance of rain, it rains on seven of those ten days. She is not always right — but her confidence is trustworthy, so you know exactly when to carry an umbrella. That property, calibration, is what turns a probability from decoration into machinery: code can auto-accept the 95%-sure decisions and route the 60%-sure ones to a person. Optimize for applause and you get an assistant that needs supervision; optimize for calibration and you get a component that can run unattended. Automation over assistance — that’s the whole company in three words.
Worth stating plainly: how RLCD actually works — the reward construction, the base model, the parameter count — is entirely undisclosed. The objective is public; the mechanism is marketing-shaped.
Is it really 0% hallucination?
Now the claim on the tin. TypeSafe markets Jev as a model that can’t hallucinate — 0%, a number that sounds like “it’s never wrong.” It means something much narrower, and you don’t need my skepticism to see it; their own blog says the quiet part out loud. Explaining the 0% in their hallucination table, they write: “Our number is not empirical. Schema matching is guaranteed, thus we can confidently add 0%.” Not empirical — they didn’t measure anything. The 0% is true by definition: a model that can only bubble in your printed options can never scribble in the margins. The Decoder spelled out the consequence: the guarantee “only covers the allowed output structure… a factually wrong choice within those options is still possible.”
And it happens. On TypeSafe’s own benchmark, Jev agrees with the right answer about 68% of the time — mid-tier LLM territory, wrong roughly one in three. Read the fine print on that benchmark too: “right” means agreement with an average of frontier models’ answers, not ground truth. So the honest sentence is: Jev fails exactly as often as a decent LLM — it just fails in-format. “0% hallucination” is a promise about the shape of the answer, never its truth.
Is that promise worthless, then? No — and this is the nuance worth keeping. In agentic systems, malformed output is a different, nastier failure class than wrong output: a hallucinated tool call or broken JSON crashes machinery, while a wrong-but-valid value flows through paths you already built error handling for. Deleting the first class entirely is real engineering value. It’s just not the miracle the marketing wants you to hear — the calibrated confidence score, if it holds up, is what’s supposed to handle the second class, telling you which third of the answers not to trust.
An organ, not a brain
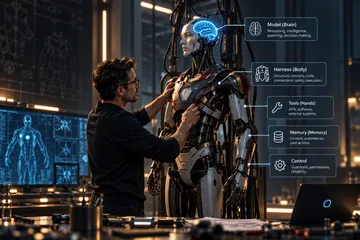
In the harness essay I described a model as a brain in a jar, and the harness as the body around it — senses, hands, spine, and reflexes. Every part of that anatomy assumed the brain talks and the body interprets.
Jev is not competing to be the brain. It has no ambition to converse, reason aloud, or write your code. What TypeSafe has built — squint at it — is a reflex, sold as a service. The knee-jerk, industrialized: fast, automatic, typed, and aware of its own uncertainty. Which team gets this ticket. Is this message angry. Should a human look at this one. Every harness is full of exactly these judgment points, currently served either by a slow, expensive detour to a chat model or by a brittle hand-built classifier.
That’s where I’d actually use it, and how I’d test their claims against my own workloads: not as a replacement for the brain, but as the twitch-speed organ at the harness’s decision joints — with the calibrated confidence deciding, at each joint, whether the reflex acts alone or wakes the brain.
The industry spent three years teaching AI to talk like us. The more interesting frontier might be teaching it to answer like software: one field at a time, with the honesty to say how sure it is.